25 published articles
AEO
You've seen them. That block of text sitting above every Google result, summarising the answer before you've clicked a single link.
AEO
B2B SaaS buyers have changed how they research. They no longer open ten browser tabs. They ask ChatGPT, Perplexity, or Gemini a direct question and act on the answer.
AEO
SEO and AEO are not the same game. SEO wins you Google blue links. AEO wins you AI citations.
AEO
Your next B2B customer is probably asking an AI right now which vendor to use. Not searching Google. Not scrolling LinkedIn. Asking ChatGPT, Perplexity, or Claude a question like: “What’s the best CRM for a 50-person SaaS company?” or “Which marketing automation platform integrates with Salesforce?”
If your company isn’t in the answer, you don’t exist for that buyer.
The shift is already here. According to a HubSpot survey of B2B buyers, 48% now use AI search while evaluating vendors. A separate survey by Responsive found that 80% of tech buyers rely on generative AI at least as much as traditional search to research vendors. These aren’t early adopters anymore — this is mainstream buying behaviour.
The problem is that most B2B companies are still optimizing for Google while their prospects have already moved on. And the rules for showing up in AI answers are fundamentally different from the rules for ranking in search.
This article explains how AI search engines actually decide which companies to recommend — and what you can do to make sure yours is one of them.
AI Search Is Not Just Faster Google
Most founders assume AI search works like Google with a chatbot interface on top. It doesn’t. The underlying mechanics are completely different, and that distinction determines whether your company gets recommended or ignored.
Google ranks pages. AI engines synthesize answers.
When a buyer asks Google “best project management software for agencies,” they get a list of ten blue links and decide where to click. When they ask ChatGPT the same question, they get a personalized, conversational recommendation — often with specific vendor names, reasons why, and comparisons — all generated from the AI’s internal understanding of the market.
That internal understanding is built from everything the model has been trained on: your website, yes, but also third-party publications, review platforms, directories, community forums, and industry databases. The AI is not crawling the web in real time for most queries. It is drawing on a synthesized model of your brand’s reputation across the entire digital ecosystem.
The key insight: Your website is your resume. AI search is calling your references. What third parties say about you matters far more than what you say about yourself.
There is also a critical overlap problem. Research shows that only about 12% of URLs cited by AI engines sit in Google’s top 10 for the same query. That means strong SEO rankings and strong AI visibility are largely independent outcomes. A company can dominate Google and be invisible to AI — and increasingly, that is exactly what is happening.
How LLMs Actually Decide Who to Recommend
When a B2B buyer asks an AI assistant to recommend a vendor, the model runs through a layered decision process. Understanding each layer is the first step to influencing the outcome.
Step 1: Entity Recognition
AI models think in terms of entities and relationships, not keywords. Before recommending your company, the model needs to “know” you exist as a distinct, clearly defined entity in your category. This means your brand name, what you do, who you serve, and how you relate to other known entities (competitors, integrations, categories) must be consistently represented across the web.
Inconsistent naming, vague positioning, or a thin digital footprint causes the model to either ignore your brand or misrepresent it. One common failure mode: a company appears in AI answers but is described in the wrong category or with outdated information because the model has conflicting signals.
Step 2: Authority and Trust Signals
Once the model recognizes your entity, it evaluates authority. This is where third-party signals dominate:
Earned media: Coverage in respected industry publications
Review platforms: G2, Capterra, Trustpilot, and similar sites
Directories and databases: Crunchbase, LinkedIn, industry-specific listings
Community mentions: Reddit threads, forums, and discussion boards
Backlinks from authoritative domains: Signals that others vouch for your expertise
The model weights these signals to determine how confidently it can recommend you. A company with deep third-party coverage gets recommended with conviction. A company that only has its own website gets skipped.
Step 3: Relevance to the Buyer’s Query
AI assistants personalize answers based on the specific context of the query. A buyer asking “best CRM for a bootstrapped SaaS startup” gets a different answer than one asking “enterprise CRM with HIPAA compliance.” The model matches your brand to queries based on how clearly your content addresses specific use cases, company sizes, industries, and pain points.
This is why broad, generic positioning hurts AI visibility. If your content doesn’t clearly signal who you’re for and what problems you solve, the model can’t confidently place you in the right answers.
Step 4: Freshness and Recency
AI models are regularly updated and increasingly use retrieval-augmented generation (RAG) to pull in current web content for time-sensitive queries. Brands that publish consistently, earn ongoing media coverage, and maintain active profiles across platforms signal to the model that they are current and relevant. Brands that went quiet two years ago may have strong historical training data but declining real-time signals.
Each AI Engine Has Different Priorities
Not all AI search engines work the same way. A B2B company visible in ChatGPT may be invisible in Perplexity, and vice versa. Understanding each platform’s bias helps you prioritize where to focus.
AI Engine | Primary Recommendation Signal | What This Means for B2B Brands |
|---|---|---|
ChatGPT | Consensus across authoritative sources | You need to appear in multiple trusted publications, not just one |
Perplexity | Real-time web search + recency | Fresh content and recent coverage matter more than historical authority |
Google AI Overviews | Google’s existing index + structured data | Schema markup and strong on-page structure amplify your existing SEO |
Claude | Training data depth + entity clarity | Clear, consistent brand definition across the web is critical |
Gemini | Google Knowledge Graph + structured data | Schema implementation has the highest priority weight (estimated 45%) |
The practical implication: A brand that appears consistently across all five platforms is far more likely to be recommended regardless of which AI a buyer happens to use. Platform-specific optimization is a second-order concern; broad authority is the foundation.
One important nuance: Perplexity runs a live web search for every query, which means it can surface newer or smaller companies that have strong recent coverage, even if they lack years of accumulated authority. For B2B companies that are earlier in their growth, this is a meaningful opportunity.
What B2B Companies Can Do About It
Understanding the mechanics is useful. Knowing what to do about them is what matters. AI visibility is not a one-time fix — it is a system that compounds over time. Here is where to start.
Build Topical Authority, Not Just Pages
AI engines favour brands that comprehensively own a topic, not brands that have one good blog post. Pick three to five core topics that directly map to your buyers’ questions and build deep, interconnected content around each one. The model needs to be able to identify your brand as the authoritative source on the problems you solve.
Earn Third-Party Coverage Systematically
Your own website is the weakest signal you can send. Industry publications, analyst mentions, review platforms, and community discussions are what AI models treat as social proof. One well-placed feature in a respected industry publication generates more AI citation weight than twenty blog posts on your own site.
Establish Clear Entity Signals
Use your exact brand name consistently across every platform — your website, LinkedIn, Crunchbase, G2, industry directories, and press mentions. Inconsistency creates ambiguity. Ambiguity means the model either skips you or misrepresents you.
Structure Your Content for AI Extraction
AI engines extract specific passages from your content to use in answers. Each section of your content should open with a clear, direct answer to a specific buyer question — not a preamble. Content structured around questions that buyers actually ask in AI prompts (“What is the best [category] for [use case]?”) is far more likely to be quoted directly.
Monitor Your Visibility Across Platforms
Most B2B companies have no idea how they appear in AI answers right now. Running your ten most important buyer queries through ChatGPT, Perplexity, Claude, and Google AI Overviews monthly is the minimum baseline. Track whether you appear, how you are described, and which competitors are being recommended instead of you.
The first-mover advantage is real. LLM perception drift, the month-over-month shift in how AI models position brands in a category, is already reshaping B2B markets. Research from Search Engine Land shows that brands like Atlassian gained significant AI visibility scores in a single month while established competitors dropped — purely based on which brands had stronger semantic anchoring in the model’s training data.
Companies that build AI visibility now are compounding an advantage that will be very difficult to close in two years.
The Window Is Open — For Now
AI search is not a future trend to monitor. It is an active buying channel where your prospects are building shortlists today. The mechanics favour companies that move early: AI models develop brand associations over time, and those associations are sticky. Brands that establish strong entity signals and third-party authority now will be the default recommendations in their categories by 2027.
The good news for B2B companies is that most of your competitors haven’t started. The AI visibility landscape in most B2B categories is still wide open. That is a narrow window.
If you want to understand where your company stands right now — which queries you appear in, how you’re described, and what it would take to move up — Windgrove AI offers AI visibility audits specifically built for B2B companies. It’s the fastest way to see your current position and build a roadmap to own it.

AEO
Most B2B founders who discover their business isn’t showing up in ChatGPT assume it’s a content problem. They think they need more blog posts, better copy, or a PR push.
Sometimes that’s true. But often, the issue is more basic: AI crawlers can’t find your site, can’t read it properly, or don’t know who you are.
Before any AEO strategy will work, your website needs a technical foundation that AI engines can actually use. Four files. None of them require a developer. All of them matter more than most people realize.
The uncomfortable truth: You can publish great content every week and still be invisible to AI engines if these four things aren’t in place. Content without infrastructure is noise.
TL;DR: The AEO tech stack has four parts:
sitemap.xml(so crawlers find your pages),robots.txt(so AI bots are explicitly allowed in), Organization schema JSON-LD (so AI engines know who you are), and[llms.txt](https://windgrove.ai/blog/llmstxt-explained-what-it-is-why-it-matters-and-why-google-now-checks-for-it)(so models get a clean, curated brief about your site). All four can be set up in under 90 minutes. None require a developer.
Here’s what makes up the AEO tech stack, why each piece exists, and what happens if it’s missing.
1. sitemap.xml: Give AI Crawlers a Map of Your Site
Your sitemap is an XML file that lists every page on your website. It tells crawlers what exists, when it was last updated, and how important each page is relative to the others.
Search engines have used sitemaps for years. AI crawlers use them too, including GPTBot (ChatGPT), Bingbot (Bing/Copilot), ClaudeBot (Anthropic), and PerplexityBot. When they land on your domain, one of the first things they look for is /sitemap.xml.
Why it matters for AEO specifically
AI engines don’t just crawl randomly. They prioritize. A sitemap with accurate lastmod timestamps signals which pages are fresh and worth indexing. Without it, crawlers have to guess, and they’ll often miss your most important pages entirely.
What happens if it’s missing: AI crawlers index whatever they happen to find. Your homepage might get picked up. Your service pages, case studies, and comparison content probably won’t.
What to check right now
Does
yourdomain.com/sitemap.xmlload?Is every important page listed (services, about, blog posts)?
Are your
lastmoddates accurate and up to date?Is the sitemap URL referenced in your
robots.txtfile?
Most CMS platforms (WordPress, Webflow, Squarespace) generate a sitemap automatically. The issue is usually that it exists but hasn’t been submitted to Google Search Console. Or the lastmod dates are stale. Both matter for AI crawl prioritization.
2. robots.txt: Tell AI Crawlers They’re Welcome
Your robots.txt file controls which bots can crawl your site and which paths they can access. It lives at yourdomain.com/robots.txt and every well-behaved crawler checks it before indexing anything.
Here’s the problem most B2B websites have: their robots.txt was set up years ago for traditional SEO. It was never updated for AI crawlers. That means GPTBot, ClaudeBot, PerplexityBot, and others may be blocked, throttled, or simply not addressed.
The crawlers you need to explicitly allow
As of 2026, the AI crawlers worth explicitly allowing in your robots.txt are:
Crawler | AI Engine |
|---|---|
| ChatGPT / OpenAI |
| ChatGPT browsing |
| OpenAI search |
| Claude / Anthropic |
| Perplexity |
| Bing / Microsoft Copilot |
| Grok / xAI |
A minimal, AI-ready robots.txt looks like this:
The distinction that matters
Not all AI bots are the same. GPTBot, for example, both trains ChatGPT’s models and powers live citations in responses. Blocking it means ChatGPT can’t cite you in real-time answers. That’s a significant visibility loss.
What happens if it’s missing or wrong: If your robots.txt blocks or doesn’t explicitly allow AI crawlers, they may not index your content at all. You can publish the best content in your category and still be invisible. This is one of the most common reasons B2B companies aren’t showing up in ChatGPT.
3. Organization Schema (JSON-LD): Prove You’re a Real Business
When an AI engine generates a recommendation, it doesn’t just pull a quote from your homepage. It synthesizes what it knows about your organization from structured, machine-readable data. That’s where JSON-LD schema markup comes in.
JSON-LD is a block of structured data embedded in your site’s <head>. It tells AI engines (and search engines) exactly who you are: your business name, what you do, where you’re located, how to contact you, and how you’re connected to other entities on the web.
For B2B companies, the Organization type is the starting point. It’s the foundation that makes everything else you publish more credible and citable.
What an Organization schema block looks like
The sameAs field is particularly important. It links your website entity to your LinkedIn, social profiles, and any directories where you’re listed. AI engines use these cross-references to verify that your business is real and consistent across the web.
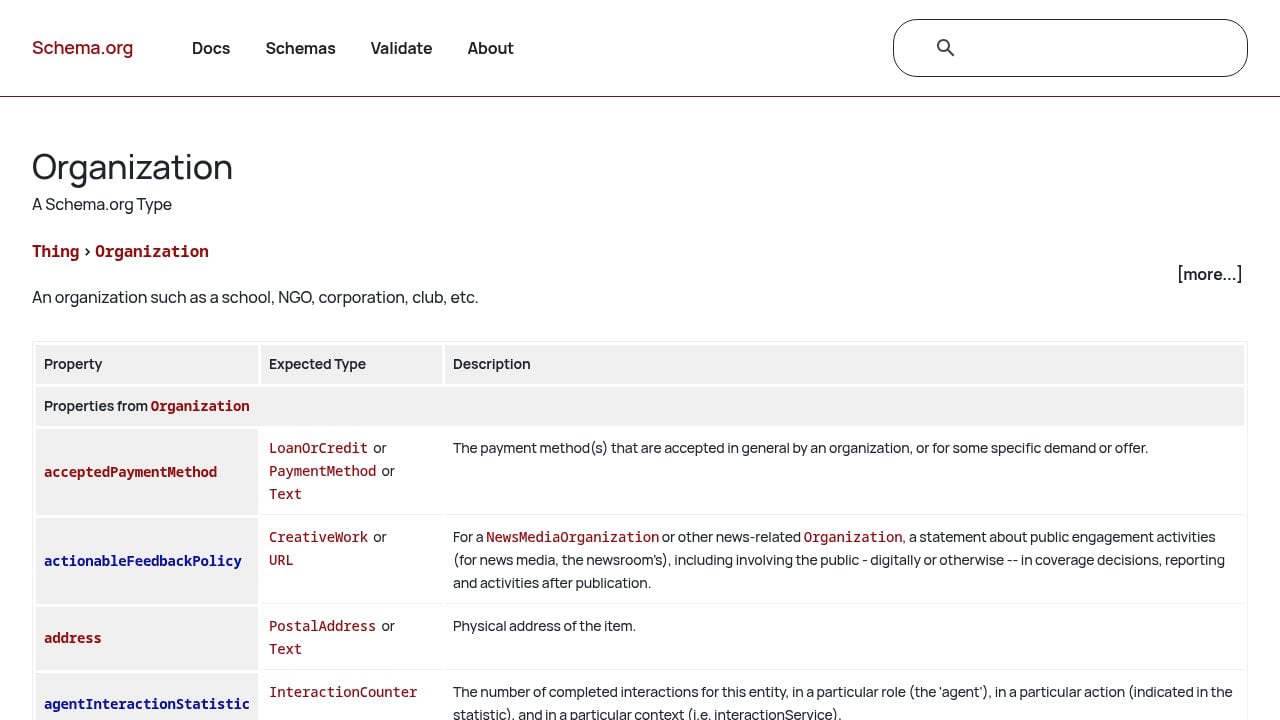
What happens if it’s missing: AI engines have to infer who you are from your page text alone. That means inconsistencies, hallucinations, and a lower probability of being cited confidently. Understanding how AI engines actually build recommendations makes it clear why schema is non-negotiable. If the AI isn’t sure about you, it won’t recommend you.
4. llms.txt: Speak Directly to AI Models
llms.txt is the newest addition to the AEO tech stack, and the one most B2B websites are still missing.
Think of it as robots.txt for large language models. It’s a plain-text file that lives at your domain root. It tells AI models exactly what your site contains, what your best content is, and where to find it. No parsing required. No inference. You’re handing the AI a curated summary in a format it can read directly.
The format is simple Markdown. A basic llms.txt for a B2B company looks like this:
Why this matters right now
llms.txt is still an emerging standard, not a universal requirement. But adoption is growing fast. AI crawlers that support it get a clean, unambiguous signal about who you are and what you offer. That reduces hallucination risk and increases the likelihood of accurate, confident citations.
The cost of adding it is about 15 minutes. The upside is a cleaner signal to every AI engine that supports it.
What happens if it’s missing: AI models piece together your identity from whatever they can scrape. Sometimes they get it right. Often they don’t. A missing llms.txt is a missed opportunity to control the narrative before the AI forms one on its own.
These Four Files Won’t Get You Recommended on Their Own
But without them, nothing else will work.
Content strategy, citation building, authority campaigns: all of it depends on AI crawlers being able to find your site, understand who you are, and trust what they find. The AEO tech stack is the prerequisite.
Here’s the full picture at a glance:
File | What it does | Time to implement |
|---|---|---|
| Maps your site for crawlers | 10-20 min (most CMS auto-generates) |
| Grants AI crawlers access | 10 min |
Organization schema | Identifies your business to AI | 20-30 min |
| Gives AI a curated site brief | 15 min |
Start with a quick audit. Go to yourdomain.com/robots.txt and yourdomain.com/sitemap.xml right now. Check whether GPTBot and Bingbot are explicitly allowed. Check whether your sitemap loads and lists your key pages. Then validate your schema at Google’s Rich Results Test.
If any of these are missing or misconfigured, that’s your answer for why AI engines aren’t recommending you.
Want to know exactly where you stand? We run a free AI Growth Audit that checks every layer of your AEO tech stack, tests your brand across ChatGPT, Perplexity, Claude, Gemini, and Grok, and shows you precisely what’s keeping you out of AI recommendations. Book yours at windgrove.ai.
AEO
Most founders who discover their company isn’t showing up in ChatGPT assume it’s a content problem. They think they need more blog posts, a PR push, or a stronger social presence. Sometimes that’s true. But more often, the issue is more fundamental: AI crawlers can’t properly read your site, don’t know who you are as an entity, or can’t extract a clean answer from your pages.
Content and citation work can’t move the needle on a technically broken foundation. This is the part most AEO conversations skip over. Before you write a single piece of AI-optimised content, your site needs to pass a basic infrastructure test.
Here are the 12 things we check in every audit, what breaking any one of them costs you in citations, and how to check where you stand today.
TL;DR
Before any content or citation work can move the needle, your site needs to be technically readable by LLMs. Most sites aren’t. The 12 infrastructure items below are what unlock AI citation. Check each one before you spend a dollar on content.
Why Technical Infrastructure Comes First
AI engines don’t browse your site the way a human does. They crawl it, parse structured signals, cross-reference your entity against third-party sources, and extract answers from your content. If any part of that chain is broken, your content never enters the citation pool, regardless of how good it is.
Think of it this way: you can write the most authoritative, well-structured answer to a target query. But if your robots.txt is blocking the crawler, or your canonical tags are pointing in the wrong direction, or your content has no author attribution, the LLM either can’t access it or doesn’t trust it enough to cite it.
The uncomfortable truth: most companies that are invisible in AI-generated answers have a technical problem, not a content problem.
The 12 items below fall into four categories:
Crawlability: Can AI systems actually access your site and the right pages on it?
Structured data: Have you told AI engines what your content is, who wrote it, and what organisation it belongs to?
Content readability: Is your content structured so that an LLM can extract a clean, citable answer?
Entity consistency: Does your brand present itself identically across every platform an AI engine might cross-reference?
Fix these before anything else. The content work compounds on top of a clean foundation. Without it, you’re building on sand.
The 12-Item Technical AEO Audit
1. robots.txt
What it is: The file that tells crawlers which pages they can and can’t access.
What breaking it costs you: If your robots.txt is blocking the crawlers that AI platforms use, your entire site is invisible to them. It doesn’t matter what’s on those pages.
How to audit it: Go to yourdomain.com/robots.txt. Look for any Disallow rules that might be blocking your key pages or entire directories. Specifically check whether you’re blocking any user-agents you don’t recognise. Many sites have legacy rules that made sense years ago and now block modern crawlers by accident.
What good looks like: Your key pages and content directories are fully accessible. You’re not running blanket Disallow rules without understanding what they’re blocking.
2. llms.txt
What it is: A newer file, analogous to robots.txt, but built specifically for LLM crawlers. It signals which content on your site is authoritative, citable, and intended for AI consumption.
What breaking it costs you: Without it, LLMs have no explicit signal about which of your pages to prioritise. They make their own inferences, which aren’t always correct.
How to audit it: Go to yourdomain.com/llms.txt. If you get a 404, you don’t have one. Most sites don’t.
What good looks like: The file exists, points to your most important pages and content, and is structured according to the llms.txt specification.
3. XML Sitemap Completeness
What it is: The map that tells search engines and AI crawlers which pages exist on your site.
What breaking it costs you: Pages missing from your sitemap are pages that LLMs may never discover. Even if those pages are technically accessible, they’re less likely to be crawled and indexed.
How to audit it: Go to yourdomain.com/sitemap.xml. Cross-reference the pages listed against the pages you actually want indexed. Look for missing blog posts, landing pages, or service pages. Also check that the sitemap is submitted in Google Search Console.
What good looks like: Every page you want cited is in the sitemap. The sitemap is current and has no broken URLs.
4. Canonical URL Resolution
What it is: Canonical tags tell crawlers which version of a URL is the “official” one when duplicates exist.
What breaking it costs you: www vs non-www conflicts, URL parameters, and canonical mismatches cause LLMs to treat your site as multiple separate entities. This splits your citation authority across versions of the same page and dilutes your overall signal.
How to audit it: Use a tool like Screaming Frog to crawl your site and flag canonical conflicts. Check that your www and non-www versions redirect to a single canonical. Look for pages where the canonical tag points somewhere unexpected.
What good looks like: One canonical version per page, consistently enforced. No conflicting signals across URL variants.
5. FAQ Schema
What it is: Structured data markup that labels individual question-and-answer pairs on your pages so AI engines can extract and cite them directly.
What breaking it costs you: Without FAQ schema, an LLM has to infer which part of your page answers a given query. With it, you’re handing the engine a pre-packaged answer it can pull verbatim. This is one of the highest-leverage schema types for AI citation.
How to audit it: Use Google’s Rich Results Test on your key pages. If FAQ schema is present and valid, it will show up. If not, it won’t.
What good looks like: Every page targeting a question-based query has valid FAQ schema. Each Q&A pair is self-contained, specific, and directly answers the question it’s paired with.
6. Organisation Schema
What it is: Structured data that tells AI engines who you are as a company: your name, URL, logo, contact information, social profiles, and founding details.
What breaking it costs you: Without it, LLMs are assembling a picture of your organisation from scattered signals. That picture is often incomplete or inconsistent, which reduces citation confidence.
How to audit it: Use Schema.org’s validator or Google’s Rich Results Test on your homepage. Check whether Organisation schema is present and whether it includes your name, URL, logo, and sameAs links to your social profiles and directories.
What good looks like: Valid Organisation schema on your homepage. All key fields populated. sameAs links pointing to your LinkedIn, Crunchbase, Google Business Profile, and any other authoritative directory listings.
7. Article Schema with Author Attribution
What it is: Structured data on your blog posts and articles that identifies the piece as an article, names the author, and includes the publication date.
What breaking it costs you: AI engines look for authorship signals when deciding whether to cite a piece of content. Anonymous content with no author attribution is treated as lower-trust. Content with a named author, credentials, and a publication date is treated as more citable.
How to audit it: Run your blog posts through Google’s Rich Results Test. Check whether Article schema is present. Look for the author field and the datePublished field specifically.
What good looks like: Every article has Article schema. The author field points to a real person with a bio page. datePublished is accurate and present.
8. H1 Direct Answers
What it is: The practice of placing a direct, concise answer to the page’s target question in the first 100 words of the content.
What breaking it costs you: LLMs look near the top of a page for extractable answers. If your content buries the answer 500 words in after a long introduction, the LLM either misses it or passes over your page in favour of one that answers the question immediately.
How to audit it: Open your key pages and read the first paragraph. Ask yourself: if someone searched for the query this page targets, is the answer clearly stated in the opening lines? Or does the page start with background, context, and scene-setting before getting to the point?
What good looks like: The first 100 words of every key page contain a direct, specific answer to the target query. No long wind-ups. No “In this article, we’ll explore…” openings.
9. Publication Dates on Content
What it is: Visible and schema-tagged publication dates on your articles and blog posts.
What breaking it costs you: AI engines use publication dates to assess content freshness and relevance. Undated content is treated as lower-confidence. For queries where recency matters, undated content often loses to dated content even when the quality is higher.
How to audit it: Go through your blog and check whether each post displays a publication date visibly on the page. Then verify that the datePublished field is present in the Article schema.
What good looks like: Every piece of content has a visible, accurate publication date. The same date appears in the Article schema. If you’ve updated a piece, the dateModified field is also present.
10. Internal Link Architecture
What it is: The network of links between your own pages that signals content relationships and helps crawlers navigate your site.
What breaking it costs you: A site with weak internal linking is a collection of isolated pages from an AI crawler’s perspective. LLMs use internal link patterns to understand which pages are most important and how topics relate to each other. Orphaned pages, or pages with no inbound internal links, are often invisible in practice even if they’re technically indexed.
How to audit it: Use Screaming Frog to map your internal link structure. Look for pages with zero or very few inbound internal links. Check whether your most important content pages are linked from multiple relevant locations across the site.
What good looks like: Key pages are linked from multiple relevant locations. Topic clusters are connected logically. No important pages are sitting as orphans.
11. Google Business Profile Consistency
What it is: Your Google Business Profile listing, which AI engines use as a primary signal for local and category-based queries.
What breaking it costs you: An incomplete, inconsistent, or unclaimed GBP means you’re invisible for category-level queries, not just location-specific ones. LLMs pull from GBP data when generating recommendations for “best [service type] in [city]” and similar queries.
How to audit it: Search for your business name in Google Maps. Check that the listing is claimed, that the business name matches exactly what’s on your website, that the description is accurate and complete, and that your hours, phone number, and URL are current.
What good looks like: Claimed, complete, and consistent. Business name, description, and contact details match your website exactly. Categories are accurate and specific.
12. Entity Alignment Across Directories
What it is: The consistency of your brand’s name, description, URL, and contact details across every platform an AI engine might cross-reference: LinkedIn, Crunchbase, Apple Maps, Bing Places, and any vertical-specific directories relevant to your industry.
What breaking it costs you: AI engines cross-reference your brand across the web before deciding how confidently to cite you. If LinkedIn says one thing, Crunchbase says another, and your website says a third, the LLM’s confidence in your entity drops. Inconsistency reads as unreliability.
How to audit it: Search your brand name across the major directories. Check that your business name is identical everywhere (not “Acme Inc.” in one place and “Acme” in another). Verify that your URL, description, and founding details are consistent.
What good looks like: Identical name, URL, and description across every listing. No outdated information sitting on platforms you forgot you signed up for three years ago.
How to Prioritise When You Find Problems
Most sites that go through this audit find issues in multiple areas. The question is where to start.
The answer depends on severity, but there’s a general order that makes sense for most sites:
Fix crawlability first. robots.txt, sitemap, and canonical issues are foundational. If crawlers can’t access your site or are getting confused about which URL is canonical, nothing else matters. These are also usually the fastest to fix.
Implement structured data next. Organisation schema, Article schema, and FAQ schema have the highest direct impact on citation probability. They’re the difference between an LLM having to guess what your content is about and being told explicitly.
Then address content readability. H1 direct answers and publication dates are content-level changes. They require going through your existing pages and reformatting. This takes time but compounds quickly once done.
Entity consistency is ongoing. Directory alignment isn’t a one-time fix. As you add new listings and update your business details, consistency needs to be maintained.
The single highest-impact fix for most sites: FAQ schema on key pages, combined with H1 direct answers in the opening paragraph. These two changes alone can move citation rates meaningfully for sites that previously had neither.
Frequently Asked Questions
Can I do a technical AEO audit myself?
Yes. Everything in this checklist is something a technically capable founder or developer can work through independently. The tools referenced here (Screaming Frog, Google’s Rich Results Test, Schema.org’s validator, Google Search Console) are all free or low-cost. The audit itself isn’t the hard part. The hard part is fixing everything you find, especially the structured data implementation, which requires adding and validating JSON-LD across your entire site. If you have a developer comfortable with schema markup, the technical fixes are manageable. If you don’t, the implementation phase is where most teams get stuck.
How long does it take to implement AEO technical fixes?
For a site with 50 to 200 pages, a thorough technical AEO implementation typically takes three to four weeks when done properly. Crawlability fixes (robots.txt, sitemap, canonicals) can be done in a day or two. Structured data implementation across all key pages is the most time-consuming part, particularly if your CMS doesn’t have native schema support. Entity alignment across directories can be done in parallel and usually takes a week of focused work. Plan for four weeks total if you’re doing this alongside other priorities.
Which technical AEO fix has the biggest impact?
FAQ schema, consistently. It’s the fix that most directly changes how AI engines interact with your content. When you add valid FAQ schema to a page, you’re giving LLMs a pre-packaged, extractable answer they can cite verbatim. Without it, they have to infer the answer from unstructured prose. That inference is less reliable and less likely to result in a citation. Pair FAQ schema with H1 direct answers in the opening paragraph and you’ve addressed the two most common reasons AI engines pass over otherwise good content.
We Handle All 12 of These in Month 1
This checklist is the foundation layer of every Windgrove engagement. Before we write a single piece of content or build a single citation, we go through all 12 of these items on your site. We fix what’s broken, implement what’s missing, and verify everything is working before the content engine starts.
Here is what that looks like in practice:
Week 1: robots.txt audit and rewrite, sitemap review, canonical conflict identification and resolution, llms.txt configuration.
Week 2: Organisation schema, Article schema, and FAQ schema implemented across your key pages. Rich Results Test validation on every page touched.
Week 3: H1 direct answer restructuring on existing content, publication date audit and correction, author attribution added to all articles.
Week 4: Google Business Profile optimisation, entity alignment across LinkedIn, Crunchbase, Apple Maps, Bing Places, and any vertical-specific directories. Internal link architecture review and gap-filling.
By the end of Month 1, your site is technically ready for AI citation. Month 2 is when the content work begins, and it compounds on a foundation that’s actually solid.
If you want to see what this looks like for your specific site, we’re happy to take a look. We’ll tell you exactly where you stand across all 12 items before any commitment.
AEO
The AEO market in 2026 has a serious pretender problem.
Traditional SEO agencies are rebranding overnight. New logos, new landing pages, same playbooks. For buyers trying to hire a genuine AI visibility partner, the noise is deafening — and the cost of choosing wrong is real budget burned while competitors quietly build the citation authority that will define AI search for the next decade.
The most reliable filter: ask for a live demonstration of a client being cited in ChatGPT, Perplexity, or Google AI Overviews right now. Not a screenshot. Not a case study PDF. A live query. That one request will cut your shortlist in half.
The ten questions below give you a complete vetting framework — covering methodology, measurement, off-site signals, deliverables, and the red flags that separate genuine practitioners from agencies that learned the acronym last quarter.
Why Vetting an AEO Agency Is Harder Than It Looks
The shift from blue-link search to AI-generated answers is one of the most consequential changes in digital marketing in a decade. Platforms like ChatGPT, Perplexity, Claude, Gemini, and Google AI Overviews now answer buyer questions directly. No list of results. No clicking around. Just an answer. For brands, this means that if an AI doesn’t cite you, you effectively don’t exist for a growing share of high-intent queries.
The problem is that the market has moved faster than the talent pool. A 2026 enterprise buyer evaluation by Onely noted that practitioners widely agree: “Most agencies claiming to do GEO are just rebranding traditional SEO with AI buzzwords.” The same pattern holds in AEO. Most agencies can implement schema markup and restructure a few pages. Far fewer understand how large language models evaluate source authority, why Perplexity cites different pages than ChatGPT for the same query, or how to build the off-site citation signals that actually move the needle.
The ten questions below are designed to cut through that noise quickly.
1. Can You Show Me Specific Queries Where a Current Client Appears in AI Answers?
This is the single most powerful vetting question available. Ask the agency to open ChatGPT, Perplexity, or Google AI Overviews right now and show you a query where a client brand is cited. Not a screenshot from three months ago. A live demonstration.
Genuine AEO practitioners can do this without hesitation. Agencies that respond with keyword rankings, traffic graphs, or vague references to “AI-ready content” without citation-level specifics are almost certainly repackaging traditional SEO services.
The bar is simple: if they can’t show citations, they can’t deliver citations.
What a good answer looks like:
They open a platform on the spot and run a query
They can name the specific content changes that earned that citation
They can show more than one client across more than one platform
2. Which AI Platforms Do You Optimise For, and How Does Your Approach Differ Across Each?
Not all AI platforms behave the same way. ChatGPT, Perplexity, Google AI Overviews, Claude, and Grok each use different retrieval mechanisms, weight different authority signals, and respond to different content structures.
Perplexity places particular emphasis on citation practices and factual accuracy verification
Google AI Overviews are heavily influenced by existing organic search authority
ChatGPT’s browsing behaviour responds differently to structured data than Perplexity’s RAG-based retrieval
Claude and Grok are growing in relevance, particularly for technology and finance audiences
Industry research consistently identifies ChatGPT, Google AI Overviews, and Perplexity as the three highest-priority platforms for B2B discovery traffic. If an agency treats all five as identical, their methodology is too shallow to produce meaningful results.
Ask them to explain the differences unprompted. A credible agency won’t need to think about it.
3. How Do You Measure AEO Success, and What Does Your Reporting Look Like?
This question immediately separates genuine AEO practitioners from agencies running traditional SEO with a new label. If the monthly report they show you consists entirely of keyword rankings, organic traffic, and backlink counts, they have not built an AEO measurement infrastructure.
Real AEO reporting tracks:
Citation frequency — how often your brand appears in AI answers
Citation quality — whether those appearances happen for high-intent, decision-stage queries
Share of voice — your brand’s presence in AI answers relative to competitors
Prompt-level visibility — which specific queries trigger your citations
Business impact — whether AI-driven traffic converts to pipeline
Growth-stage companies typically invest $5,000 to $20,000 per month for comprehensive AEO services. The reporting framework needs to justify that investment with commercial metrics, not vanity numbers.
Red flag: Any agency whose sample report looks identical to a standard SEO dashboard is telling you exactly what they are actually doing.
4. How Do You Handle Off-Site Signals Like Third-Party Mentions, Reviews, and Digital PR?
AI search engines do not only pull from your website. They draw from the entire web — G2 reviews, Reddit discussions, Wikipedia entries, Capterra listings, industry publications, and digital PR placements. An agency focused exclusively on your own domain is optimising a small fraction of what AI platforms actually reference when generating answers.
Credible AEO agencies actively manage third-party platform presence as a core service, not an afterthought. That includes:
Structured management of review platforms (G2, Capterra, Trustpilot)
Targeted outreach to publications that AI models already cite
Building brand mentions across authoritative external sources that signal trustworthiness to large language models
If an agency’s entire scope of work is limited to your own domain, push back hard on that gap. The off-site signal layer is where a significant portion of AI citation authority is actually built.
5. Can You Explain How Retrieval-Augmented Generation Affects Your Content Strategy?
Retrieval-Augmented Generation (RAG) is the technical mechanism by which most AI platforms retrieve and synthesise information from the web before generating a response. Understanding RAG is foundational to effective AEO — it explains why certain content formats get cited, why answer-first structure matters, and why content that buries the key point in paragraph four rarely gets pulled into AI responses.
Ask any agency you are vetting to explain RAG and its practical implications for content strategy. Then ask them why Perplexity cites different pages than ChatGPT for the same query.
If they cannot answer fluently, their AI knowledge is superficial. This is not an obscure technical question. It is the foundation of the discipline they are claiming to practise.
What a strong answer covers:
How RAG retrieval differs from traditional crawl-and-index
Why answer-first content structure improves extraction probability
How different platforms weight recency, authority, and format differently
6. What Does Your Content Structure Approach Look Like?
The way content is structured is one of the most direct levers in AEO. AI systems are built to extract and cite answers efficiently. Content that leads with a clear, direct answer in 40 to 60 words, followed by supporting detail, is structurally optimised for extraction. Content that builds slowly to its main point, relies on storytelling, or buries conclusions is systematically disadvantaged.
A competent AEO agency should describe a specific answer-first content methodology. They should also cover schema markup beyond the basics.
Schema type | Why it matters for AEO |
|---|---|
FAQ | Directly maps to question-based AI queries |
HowTo | Structured steps are highly extractable |
Product / Review | Signals commercial context to AI engines |
Article / BlogPosting | Establishes content type and authorship |
Organization | Builds entity trust across platforms |
Ask to see examples of content they have produced for clients. Generic blog posts with no answer-first structure are a warning sign. The best agencies will show you the before-and-after of a page they restructured and explain exactly what changed and why.
7. Is AEO a One-Time Project or an Ongoing Programme?
Any agency that positions AEO as a one-time setup project either does not understand how AI search engines work, or is underselling the engagement to close the deal.
AI models update constantly. Content authority decays. Competitors are actively building citation signals every week. The brands that compound their AI visibility over time are those running continuous optimisation programmes, not those who did a one-time audit two years ago.
The ongoing work in a legitimate AEO programme includes:
Regular content audits to identify citation decay
Competitive monitoring to track share of voice shifts
Prompt-level tracking to surface new query opportunities
Iterative technical improvements as AI platforms evolve their retrieval mechanisms
Off-site signal building that compounds month over month
If an agency cannot describe what the month-six or month-twelve engagement looks like in concrete terms, that is a significant gap. Press them on it.
8. How Do You Approach Competitive Positioning in AI Answers?
Getting cited by AI is not just a technical problem. It is a positioning problem.
AI models do not simply retrieve the most technically optimised page. They cite the source that best answers the query in the context of what the user is trying to accomplish. That means an agency needs to understand why customers choose your brand over competitors, and then translate that differentiation into structures that AI engines trust.
Most agencies start with keywords. The best ones start with a more fundamental question: why do customers actually choose you?
If your competitive positioning is unclear, your AI visibility will reflect that confusion. Ask the agency how they map competitive positioning before touching content or schema, and what their process looks like for identifying the specific claims you can credibly make that will resonate with both AI systems and the buyers they serve.
The agencies worth hiring treat positioning as a prerequisite, not an afterthought.
9. What Are Your Deliverables in the First 30 to 60 Days?
Vague timelines are a consistent red flag. Agencies that cannot describe what they will ship in the first 30 to 60 days — or that hide behind “SEO takes 12 to 18 months” without interim checkpoints — often go into autopilot mode after securing the retainer.
The early weeks of an engagement should produce concrete, verifiable work:
A baseline audit showing current AI visibility across platforms
A competitive citation analysis identifying where competitors are being cited and why
A structured content and schema roadmap with prioritised pages
Initial technical fixes on high-value pages
Citation tracking infrastructure set up and running
Ask for a written scope of deliverables with dates. A credible agency will welcome this request. One that pushes back or offers only vague commitments is signalling how the rest of the engagement will go.
The first 60 days should establish a measurable baseline and produce at least one visible improvement in citation tracking data.
10. Do You Guarantee Specific AI Citation Positions?
If the answer is yes, walk away.
There are no stable first positions in AI-generated answers. AI responses change based on prompt phrasing, user location, recency signals, conversational context, and model updates that happen without notice. No agency controls how AI systems select and cite sources — and any agency claiming otherwise is either being dishonest or demonstrating a fundamental misunderstanding of how generative platforms work.
The legitimate goal of AEO is to build durable authority signals that increase the probability of citation across a wide range of relevant queries over time. That is a compounding, measurable process — but it is not a guaranteed outcome for any specific query.
An agency that is honest about this, and can explain the mechanisms behind citation probability, is demonstrating exactly the kind of expertise worth paying for.
Honest framing sounds like: “We can’t guarantee you appear for query X, but we can show you how we’ve systematically improved citation frequency for clients in your category over six months.”
Making the Decision
The AEO market in 2026 rewards buyers who ask hard questions early. The agencies worth hiring will welcome every question in this list — they will have specific answers, live proof, and a clear methodology they can articulate without preparation. The ones to avoid will deflect to traffic graphs, promise positions they cannot guarantee, and treat your website as the only variable that matters.
AEO is still a young discipline. No standardised measurement frameworks exist across the industry, and methodologies are evolving as generative platforms update their retrieval mechanisms. That makes the quality of the agency you choose more consequential, not less.
A partner with genuine expertise compounds your AI visibility over time. A pretender burns budget while your competitors build the authority signals that will define AI search for the next decade.
Frequently Asked Questions
What is the difference between AEO and SEO? SEO optimises for search rankings and organic clicks in traditional search engines. AEO optimises for citations and recommendations in AI-generated answers from platforms like ChatGPT, Perplexity, and Google AI Overviews. The two disciplines overlap significantly — strong technical SEO and authoritative content are foundational to both — but AEO adds specific layers around answer-first content structure, schema depth, off-site citation signals, and multi-platform visibility tracking that traditional SEO does not address.
How long does it take to see results from AEO? Most credible AEO agencies set expectations of three to six months before citation frequency shows meaningful improvement, with compounding gains in months six through twelve. The timeline depends on your current domain authority, competitive landscape, and how aggressively the agency is building off-site citation signals alongside on-page optimisation. Any agency promising significant results within 30 days is overpromising.
What budget should we expect for AEO services? Growth-stage companies typically invest between $5,000 and $20,000 per month for comprehensive AEO programmes. Enterprise implementations run higher depending on site complexity and the number of AI platforms being targeted. Standalone technical audits start around $5,000. Strategy-only engagements without execution support are generally less valuable because they introduce friction between insight and implementation.
Can we do AEO in-house? Teams can handle foundational work like schema markup, answer-first content restructuring, and basic citation tracking. The harder parts — understanding how AI models evaluate competitive positioning, building off-site authority signals across the sources AI platforms already trust, and interpreting prompt-level visibility data — require specialised expertise that most in-house teams have not yet developed. A hybrid model, where an agency handles strategy and technical depth while in-house teams manage content production, often delivers the best cost-to-impact ratio.
Which AI platforms should we prioritise for AEO? For most B2B companies, the priority order is ChatGPT, Google AI Overviews, and Perplexity, as these three platforms drive the largest share of discovery traffic for commercial queries. Claude and Grok are growing in relevance and worth tracking, particularly for technology and finance audiences. An agency should be able to show you where your brand currently stands across all five platforms before recommending where to focus first.
AEO
During Cloudflare’s Agent Week in April 2026, their engineering team scanned the top 500,000 domains on the web and asked a simple question: are these sites ready for AI agents? The answer was blunt. Most are not. And the coverage that followed mostly missed the point, burying smaller site owners under a list of protocols they will never need.
This article cuts through that. If you run a content site, a blog, or a simple marketing website, here is what actually matters and what you can safely ignore.
Executive Summary
AI agents are already visiting your website, but 80% of what they receive is noise: CSS, JavaScript, navigation markup, and boilerplate your content never asked for.
Cloudflare’s research found that only 4% of sites declare AI usage preferences and just 3.9% support markdown delivery, the two changes with the clearest impact for content sites.
Most agent-readiness guides treat every website the same. They should not. Content sites need three things: better discoverability, cleaner content delivery, and deliberate crawl governance.
Implementing agent-readiness features without understanding the SEO implications is how you gain AI visibility and lose Google rankings at the same time.
Why Agent Readiness Is No Longer Optional
When an AI agent visits your site, it does not see what you see. It sends an HTTP request, receives a response, and tries to extract meaningful content from whatever comes back. On a typical modern website, that response is mostly structural debris: navigation menus, JavaScript bundles, cookie consent banners, footer links, and CSS that exists purely to make things look good for humans.
Cloudflare’s Agent Readiness research measured this directly. Their finding: roughly 80% of a standard HTML response is irrelevant to an AI agent. The agent only wants the actual content. Everything else is token waste, and tokens cost money and time on the agent’s side.
This is not a niche problem. By early 2026, AI training crawlers alone accounted for nearly 50% of total web traffic. Coding assistants like Claude Code and OpenCode already send Accept: text/markdown headers with their requests, signalling that they prefer a cleaner format. Your site either responds usefully or it does not.
What it means for you: Your website has an AI audience right now, whether you have optimised for it or not. The question is not whether to act. It is which actions are worth your time.
Not Every Standard Applies to Your Site
The most important thing Cloudflare’s research confirmed is something the broader coverage glossed over: different site types need different standards. A content site and an API-first product have almost nothing in common from an agent’s perspective.
For a blog, publisher site, or marketing website, an agent has one job: find your pages, understand what they cover, and extract the content efficiently. There is no API to authenticate against, no MCP server to discover, no commerce layer to negotiate with.
The table below maps which standards actually apply to each site type.
Standard | Content Site | API-Heavy Product |
|---|---|---|
robots.txt + AI usage signals | Yes, high priority | Yes, high priority |
sitemap.xml | Yes, high priority | Yes, high priority |
llms.txt | Yes, useful | Useful for docs |
Markdown content negotiation | Yes, if stack supports it | Yes, if stack supports it |
API Catalog (RFC 9727) | No | Yes |
OAuth / auth discovery | No | Yes |
MCP Server Card | No | Yes, if you have an MCP server |
Commerce / payment protocols | No | Only if you sell access programmatically |
A content site that scores poorly on API Catalog and MCP checks is not failing. It is being evaluated by the wrong criteria.
What it means for you: If you run a content site, you can ignore the bottom four rows of that table entirely. That eliminates roughly half the “agent readiness” checklist most guides push on you.
The Three Changes That Actually Move the Needle
Cloudflare’s scan found that 78% of sites already have a robots.txt file. But the vast majority were written for traditional search crawlers, not AI agents. Only 4% declare any AI usage preferences. Just 3.9% support markdown content negotiation. The gap between “technically has a robots.txt” and “is actually agent ready” is where most smaller sites are sitting.
Here is where to focus first.
1. Fix your discoverability layer
Before an agent can read your content, it has to find it. Three things govern this.
robots.txt audit: Many sites added blanket AI-blocking rules during the training data concerns of 2023 and 2024 and never revisited them. If you want AI search visibility, check whether you are accidentally blocking GPTBot, ClaudeBot, or PerplexityBot. Blanket blocks hurt AI citation potential without stopping the crawlers you actually want to keep out.
sitemap.xml health: Agents use sitemaps the same way Google does: as a shortcut to find your pages without parsing every link in your HTML. Make sure yours is current, submitted to Google Search Console, and includes your highest-value content.
Content signals: A newer robots.txt extension lets you declare AI usage preferences at a granular level. You can allow AI search while restricting AI training. Only 4% of sites use this today, which means early adopters have a clear first-mover window.
2. Make your content easier for agents to consume
Even when agents find your pages, Cloudflare’s markdown research shows they receive up to 80% token waste in a standard HTML response. Markdown delivery eliminates most of that. Fewer tokens means faster processing, lower cost on the agent’s side, and a higher chance your content gets read in full rather than truncated by context window limits.
Your two options:
llms.txt: A plain-text file at your site root that gives agents a structured reading list of your most important pages. Think of it as a sitemap written for an LLM. Low effort, no engineering required. Start here if you have limited dev resources.
Markdown content negotiation: Agents send an
Accept: text/markdownheader and your server (or CDN) converts HTML to markdown on the fly. More powerful, automatically stays current, but requires platform support or a developer to set up.
3. Add structured data to your key pages
AI agents and crawlers use schema markup to understand what a page is about without inferring it from prose. For content sites, the highest-value schema types are Article, FAQPage, HowTo, and Organization. Beyond schema, semantic heading structure matters: a page with a clear H1, logical H2 sections, and concise opening paragraphs is dramatically easier for an agent to extract and cite accurately.
What it means for you: These three changes improve both SEO and agent readiness simultaneously. None of them require you to build anything new. They work with your existing content and architecture.
Where Agent Readiness Can Hurt SEO If You Do It Badly
This is the section most guides skip entirely. And it is the one that costs teams the most.
Agent readiness is an early-stage practice. Some of the standards being discussed today are less than a year old. Some will not survive. In the rush to implement everything, teams are making changes that improve their agent readiness score while quietly damaging their search performance. One participant at Cloudflare’s Agent Week put it plainly: sites implementing agentic features have seen measurable SEO penalties, gaining AI traffic while losing Google rankings.
The most common failure modes:
Unblocking AI crawlers without thinking it through. If you added blanket blocks in 2023, reversing them carelessly can expose content you never intended to share. Be surgical, not sweeping.
Creating new public URLs without indexation controls. Some implementations generate separate markdown endpoints at new URLs. If those are publicly accessible and not excluded from your sitemap, search engines may index them as thin or duplicate content.
Serving different content to agents vs humans. Markdown content negotiation responds to a format request, not a user-agent check, so it is technically not cloaking. But if your markdown version strips sections, changes headings, or omits context that exists in the HTML version, you have a content equivalence problem. Both search engines and AI systems penalise inconsistency.
Burning crawl budget on unnecessary infrastructure. New files, new endpoints, and new discovery mechanisms all cost crawl budget. For smaller sites with limited crawl allocation, this can slow down how quickly Google discovers your actual content.
What it means for you: Implement one change at a time. Check your search performance after each one. The goal is a site that works for both audiences, not one that gains AI visibility at the expense of the rankings you already have.
What to Implement Now, Later, or Never
Use this framework to prioritise based on your site type and available resources. Every row has been filtered for content sites specifically.
Implement Now | Implement If Relevant | Ignore For Now |
|---|---|---|
robots.txt audit (AI crawler rules) | llms.txt (if you publish infrequently) | API Catalog (RFC 9727) |
sitemap.xml health check | Markdown content negotiation (if your platform supports it) | OAuth / auth discovery |
Semantic heading structure (H1, H2, H3) | Content signals in robots.txt | MCP Server Card |
JSON-LD schema (Article, FAQ, HowTo, Org) | Link headers for key resources | Web Bot Auth / signed bot identity |
Answer-first content formatting | llms-full.txt (for large content archives) | Commerce / payment protocols (X.402) |
Implement Now applies to virtually every content site regardless of size. These changes improve both SEO and agent readiness simultaneously, carry no meaningful risk, and require no new infrastructure.
Implement If Relevant depends on your publishing cadence, hosting platform, and engineering capacity. If you publish weekly, llms.txt will go stale fast. If your CDN supports markdown delivery with a toggle, turn it on.
Ignore For Now is not a permanent verdict. These standards matter for API products, developer tools, and transactional platforms. But if you run a content site, none of them apply to your architecture today.
What it means for you: The “Implement Now” column is your entire to-do list for the next 30 days. Everything else can wait until the standards mature.
Audit Your Site in 30 Minutes
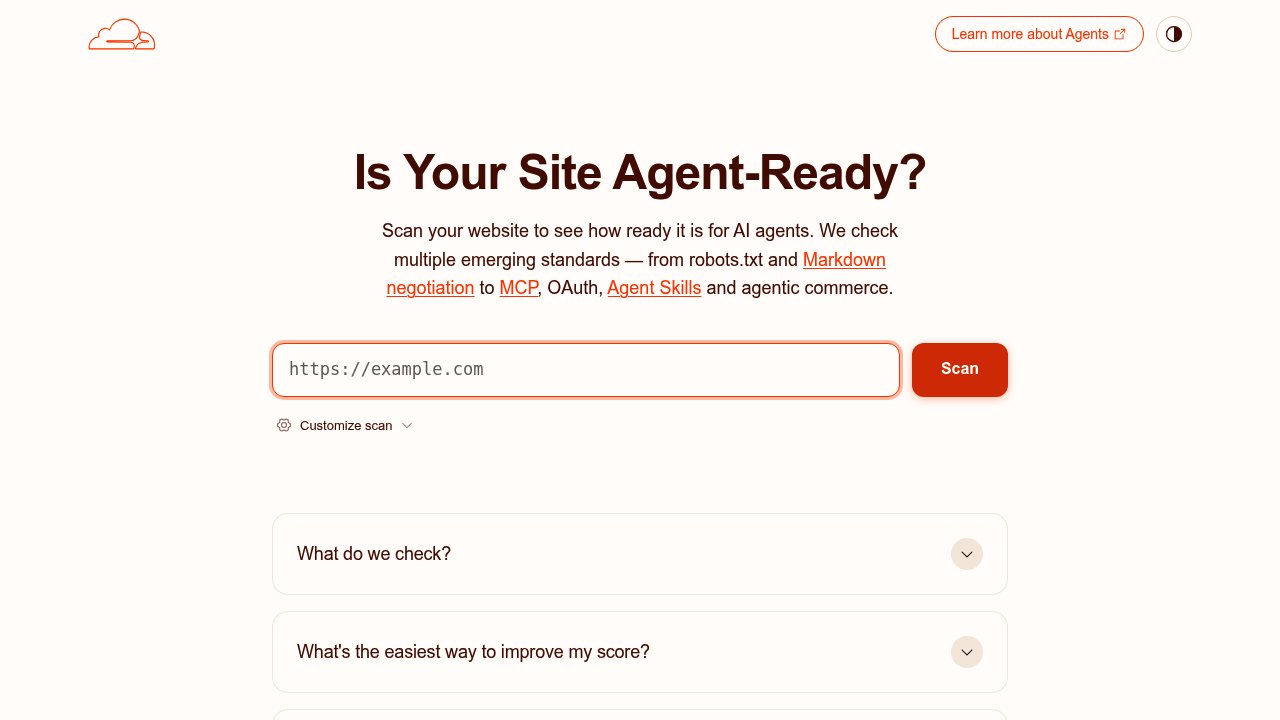
The fastest baseline is Cloudflare’s Is It Agent Ready tool. Enter your URL, select your site type, and it runs 16 checks across discoverability, content, bot access control, and capabilities in about 30 seconds. Critically, it also lets you customise the scan by site type, so a content site is not penalised for missing an MCP Server Card it was never meant to have.
Once you have your score, work through this checklist before making any changes.
Discoverability
Open your robots.txt. Are you accidentally blocking GPTBot, ClaudeBot, or PerplexityBot where you want visibility?
Is your sitemap.xml current and submitted in Google Search Console?
Does your sitemap include your highest-value content pages?
Content
Do your top 10 pages have clear H1 headings, logical H2 structure, and concise opening paragraphs?
Do key pages have Article, FAQ, or HowTo schema? Check with Google’s Rich Results Test.
Is an llms.txt file worth adding given how often you publish?
Governance
Have you decided your AI usage stance: AI search allowed, AI training restricted, or both allowed?
If you have added any new agent-facing URLs or files, are they handled correctly in your crawl directives?
Pick one improvement from each category. Implement it. Re-test. Then expand. Agent readiness is not a one-time sprint.
What it means for you: A 30-minute audit gives you a clear, prioritised list of what to fix. Most content sites will find two or three quick wins that take less than an hour to implement.
Frequently Asked Questions
Do I need to implement every agent-readiness standard to see results?
No. For content sites, the standards that matter are robots.txt governance, sitemap health, structured data, and optionally llms.txt or markdown delivery. Standards like API Catalogs, MCP Server Cards, OAuth discovery, and commerce protocols are designed for API-first products and transactional platforms. Implementing them on a content site adds complexity without any meaningful benefit.
Will adding llms.txt improve my rankings in AI search engines?
Not directly, and not on its own. llms.txt helps agents navigate your site more efficiently, but it does not guarantee citation or ranking. What actually drives AI citation is the quality and clarity of your content: clear headings, concise paragraphs, structured data, and answer-first formatting that lets agents extract useful information without guessing. llms.txt is a useful complement to good content, not a substitute for it.
Can implementing agent-readiness features hurt my Google rankings?
Yes, if done carelessly. The most common risks are creating new public URLs for agent-facing content without proper indexation controls, serving meaningfully different content to agents versus humans, and burning crawl budget on infrastructure that Google has to process before it reaches your real pages. Implement changes one at a time and monitor your search performance after each one.
Is markdown content negotiation the same as cloaking?
Technically no. Cloaking means serving different content based on who is requesting it (typically by user-agent). Markdown content negotiation responds to a format preference declared in the HTTP Accept header, which is a standard web mechanism used for language negotiation and image format selection. The same content is served in a different format. That said, if your markdown version omits sections or changes the substance of your HTML version, you are creating a content equivalence problem that search engines and AI systems can both flag.
How do I know if AI agents are already visiting my site?
Check your server logs or analytics for known AI crawler user-agents: GPTBot (OpenAI), ClaudeBot (Anthropic), PerplexityBot, and OAI-SearchBot are the most common. Most analytics platforms do not filter these by default, so you may need to look at raw log data. Cloudflare’s dashboard also shows AI bot traffic if your site runs through their network. If you want to know how AI engines currently perceive and cite your brand specifically, Windgrove’s AI visibility audit gives you a structured read on that.

AEO
TL;DR SEO and AEO are not competing budget lines. SEO keeps you visible in traditional search. AEO makes you citable inside AI-generated answers from ChatGPT, Perplexity, Google AI Overviews, and Gemi
AEO
TL;DR In-house AEO requires a full content and technical team, a six-month minimum to show results, and ongoing investment in specialist tooling. It makes sense at scale. An AEO consultant gives you a
AEO
The truth is your buyers are using AI to shortlist vendors. They type a question into ChatGPT, Perplexity, or Google AI Overviews and get a confident, well-structured answer that names three or four c
AEO
Most businesses aren't showing up in ChatGPT because they've built their digital presence for Google, and Google and ChatGPT are fundamentally different engines with different credibility signals. The
AEO
Your next B2B customer is probably asking an AI right now which vendor to use. Not searching Google. Not scrolling LinkedIn. Asking ChatGPT, Perplexity, or Claude a question like: "What's the best CRM
AEO
Search has always been about getting found. For decades, that meant ranking on Google, earning clicks, and driving traffic to your website. But that model is changing faster than most businesses reali

AEO
TL;DR AI tools don't cite randomly. They pull from five specific signals: structured data, third-party validation, answer-formatted content, entity consistency, and funnel-stage coverage. Most SaaS co
AEO
Executive Summary AI answer engines do not discover brands by crawling random websites. They pull from a concentrated set of trusted publishers, directories, review platforms, and community forums tha

AEO
Executive Summary HowTo schema and Article schema send fundamentally different signals to AI engines. Applying the wrong one to your content is one of the most common and costly structured data mist
AEO
Executive SummaryChatGPT does not rank pages — it synthesizes answers. A product page built for Google keyword rankings will not automatically earn AI recommendations; it requires a different structur
AEO
Executive Summaryllms.txt is a plain-text file that lives at the root of your website and tells AI crawlers what your site is about, which pages matter, and how to read your content efficiently.As of

AEO
AEO is now a distinct buying category in Canadian search marketing. Not every agency offering it was built for it. This guide ranks 10 Canadian agencies by one criterion that most roundups ignore: whe
AEO
AEO competitor benchmarking is the process of systematically measuring how often your competitors appear in AI-generated answers, which queries they own, and what signals are driving their citations,
AEO
During Cloudflare's Agent Week in April 2026, their engineering team scanned the top 500,000 domains on the web and asked a simple question: are these sites ready for AI agents? The answer was blunt.

AEO
The AEO market in 2026 has a serious pretender problem. Traditional SEO agencies are rebranding overnight. New logos, new landing pages, same playbooks. For buyers trying to hire a genuine AI visibili

AEO
Most marketing teams shopping for an agency in 2026 are asking the wrong question. They ask, "Do you do AEO?" Both types of agencies say yes. The question that actually separates them is: "Was your en
AEO
Executive Summary B2B SaaS buyers have changed how they research. They no longer open ten browser tabs. They ask ChatGPT, Perplexity, or Gemini a direct question and act on the answer. According to Ga